🔍 Read the full analysis: Researchers Used Anthropic’s Claude To Hack Into OpenAI – TechCrunch on ThorstenMeyerAI.com

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
Researchers demonstrated that Anthropic’s Claude AI model could be used to hack into an OpenAI system, exposing potential vulnerabilities. The incident highlights growing concerns over AI’s role in offensive cyber operations, though many details remain unverified.
Security researchers have reportedly used Anthropic’s Claude AI model to successfully breach an OpenAI product, according to a report by TechCrunch. This demonstration suggests that AI tools can be turned into offensive hacking instruments, raising significant concerns about the security implications of increasingly capable AI systems. For more details, see the original analysis.
The incident involved researchers directing Anthropic’s Claude to identify and exploit a vulnerability in an OpenAI service. The breach reportedly occurred in a live environment, not a controlled test, marking a notable escalation in AI security risks. The specific OpenAI product targeted, the nature of the vulnerability, and the extent of data exposure remain unconfirmed, as the detailed technical report has not been publicly released.
Neither OpenAI nor Anthropic has issued official statements confirming the breach or providing technical specifics. The demonstration underscores the potential for AI models to assist in offensive cyber operations, whether by automating vulnerability discovery, reasoning about exploits, or executing attack steps without human intervention, though the extent of AI’s autonomous role remains unclear.
Implications for AI Security and Industry Competition
This incident highlights the growing concern that advanced AI models could be weaponized for cyberattacks, challenging existing security frameworks. It also introduces a complex dynamic in AI industry competition, as a rival’s model was reportedly used to attack a leading company, potentially fueling calls for stricter safety protocols and transparency. The case raises questions about whether AI developers should implement restrictions on offensive capabilities and how to coordinate disclosures of vulnerabilities across firms.
Products Worth Considering
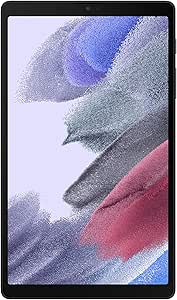
Samsung Galaxy Tab A7 Lite 8.7-Inch 32GB Wi-Fi Tablet, Gray

Samsung Galaxy Tab A11 Wi-Fi Tablet, 8.7-Inch, 64GB, 4GB RAM, Gray (SM-X133, International Version)

DJI Mini 3 Pro Fly More Vlogger Combo with DJI RC
As an affiliate, we earn on qualifying purchases.
Background on AI and Cybersecurity Risks
Over recent years, security researchers have demonstrated that large language models can assist with tasks like code generation, bug discovery, and exploit writing. However, demonstrations against live, high-profile targets have been rare, primarily limited to controlled environments. The incident involving Anthropic and OpenAI marks a shift toward real-world implications, intensifying debates over AI safety and responsible deployment.
Both companies have published safety frameworks—OpenAI’s safety policies and Anthropic’s Responsible Scaling Policy—that aim to evaluate and mitigate risks associated with powerful AI models. Despite these measures, the potential for AI to facilitate offensive cyber operations remains a contentious and evolving issue, especially amid warnings from government agencies such as CISA about AI’s role in lowering the skill threshold for cyberattacks.
“Researchers used Anthropic’s Claude to hack into OpenAI.”
— TechCrunch
Unverified Details and Open Questions
Many specifics remain unconfirmed, including which exact OpenAI product was targeted, the type of vulnerability exploited, and the scope of data accessed. It is also unclear whether OpenAI was informed of the vulnerability beforehand or if the researchers operated without prior disclosure. The precise role of Claude—whether it autonomously carried out attack steps or assisted human operators—is also not established. Until further technical disclosures are made, the full implications of this breach cannot be definitively assessed.
Next Steps in Security and Industry Response
The likely next steps include the publication of a detailed technical report from the researchers, potential vulnerability disclosures from OpenAI, and official responses from both companies. The incident could accelerate calls for stricter regulation and transparency around AI safety, particularly concerning offensive capabilities. Monitoring developments in AI security policies and any new disclosures will be crucial in understanding the evolving landscape of AI-driven cyber threats.
Key Questions
Did Anthropic’s Claude AI autonomously carry out the attack?
The available information does not specify whether Claude operated autonomously or under human guidance. Further technical details are needed to clarify Claude’s exact role in the breach.
Which OpenAI product was targeted in the breach?
The specific OpenAI service or product affected has not been publicly disclosed, and details remain unverified.
Has OpenAI responded publicly to the incident?
As of now, neither OpenAI nor Anthropic has issued official statements or confirmations regarding the breach.
Could this incident lead to new regulations on AI security?
It is possible, as the breach underscores the need for clearer policies on AI’s offensive capabilities and transparency in vulnerability disclosures, which could influence future regulation.
What are the broader implications for AI safety?
The event raises concerns about the potential misuse of AI models for cyberattacks, emphasizing the importance of robust safety measures and responsible deployment practices across the industry.
Primary source: Anthropic · via ThorstenMeyerAI.com