TL;DR

Get business pricing on tech for your team
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Liquid AI released two open-weight decision models: d1-3B for text and images, and experimental d1-omni-600M for text plus images or audio. The company reports sub-50-millisecond answers for d1-3B on four tested edge devices, but has not published speed figures or vision and audio decision benchmarks for the smaller model.
Liquid AI has released two open-weight decision models, d1-3B and experimental d1-omni-600M, designed to return structured answers from text and multimodal inputs. The company says d1-3B can answer a question in 16 to 50 milliseconds on four tested edge devices, a performance claim relevant to developers building applications that need decisions locally rather than a lengthy generated response.
The models belong to Liquid AI’s d1 decision model family and are built on the company’s Liquid Foundation Models. Unlike generative models that produce a sequence of tokens, Liquid AI says these systems return an answer in a single forward pass. The company presents them for tasks such as classification, routing, scoring and question answering, where a developer defines the output structure.
d1-3B is based on the LFM2.5-VL-3B vision-language model and accepts text and images. d1-omni-600M is based on the LFM2.5-Encoder-350M and uses vision and audio encoders; it accepts text with an image or text with audio. Liquid AI describes the 600-million-parameter model as an early research release that remains under development.
On the company’s reported Decision Index 0.2.1 results, d1-3B scored 48.57, ahead of the tested 4B and 9B models and Decider 35B-A3B, which scored 47.11. Across seven public datasets covering areas including reading comprehension, toxicity detection, intent classification, medical question answering and cross-lingual understanding, Liquid AI reports mean scores of 82.9 for d1-3B and 78.4 for d1-omni-600M. The company’s table lists 81.1 for Decider 4B and 77.1 for Decider 2B.
Local Decisions on Edge Devices
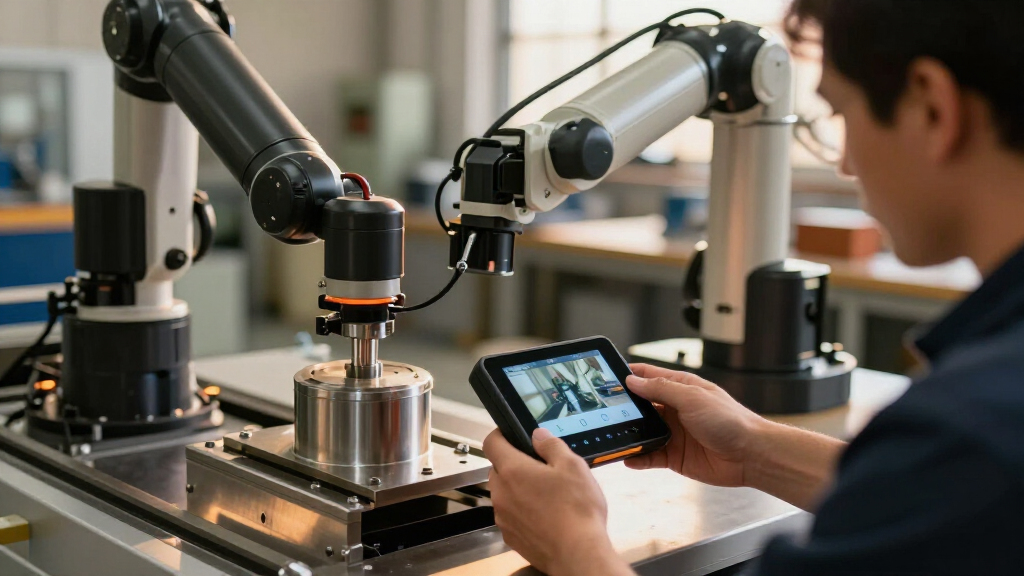
The release targets applications where sending every input to a remote service may add delay, require network access or involve sharing data outside a device. On-device inference could let developers classify a support request, route a ticket or interpret an image close to where the data is produced. Liquid AI’s reported timings give an indication of how quickly d1-3B may handle these kinds of defined tasks on selected hardware.
The results are company-reported measurements, not guarantees for every deployment. Latency can vary with input size, software configuration, batching and the task itself. Still, the combination of text-and-image input, compact model size and sub-50-millisecond single-question results on the tested Jetson devices makes the release relevant to robotics, embedded systems and other edge applications. Developers will need to test performance and accuracy against their own workloads before relying on it.
As an affiliate, we earn on qualifying purchases.
How the Models Differ
The two releases make different trade-offs. The 3B model is the larger option, built on a vision-language backbone and intended to handle text and image inputs. The 600M model has a smaller parameter count and adds an audio pathway, but its release is explicitly experimental. Liquid AI says it has not published speed results for d1-omni-600M because development is ongoing.
For d1-3B, Liquid AI reports testing with NVIDIA inferences on a GeForce RTX 4090, Jetson AGX Thor, Jetson AGX Orin 64 GB and Jetson Orin Nano, as well as an Apple M5 Pro and AMD MI325X. The company reports one-question times of 16 ms on the Thor, 26 ms on the Orin and 50 ms on the Orin Nano. It also reports that processing three questions took 20 ms on the Thor, compared with 16 ms for one question, using its stated test setup.
The company says both models are available as open weights on Hugging Face. Its example for d1-3B uses Transformers version 5.14 or later and requires loading model-provided code with a trust setting. That implementation detail matters to teams evaluating how to integrate the release and review its code and dependencies.
““Unlike our generative models, decision models don’t produce tokens but answer in a single forward pass.””
— Liquid AI
As an affiliate, we earn on qualifying purchases.
Benchmark and Deployment Gaps
The published figures do not settle how well the models perform across real-world applications. Liquid AI’s seven-dataset table reports several text-oriented task results, but the release includes no vision or audio decision benchmark scores. The company says the Decision Index version it references includes only a private vision split, while audio decision benchmarks are still an open problem. Claims about multimodal capability therefore are not accompanied by comparable public decision-task results in this release.
The speed measurements also reflect a specific set of devices and test conditions. The supplied report gives timings for named workloads, including a single question, three questions, a 3.4K-token state and a 384-pixel image, but does not establish performance for every input, application or hardware configuration. Independent evaluations and further detail on accuracy in production settings would help establish how the results translate beyond the reported tests.
It is also unclear when d1-omni-600M will leave its early research stage, whether it will receive speed measurements, or how its capabilities compare on publicly reproducible audio and vision decision tasks. Liquid AI does not provide a release timetable for those developments.
audio and image processing hardware
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Further Testing and Model Development
Developers can download the open-weight models from Hugging Face and try demonstrations in Liquid AI’s System One Arcade. The company’s release includes an integration example for d1-3B; it points users to the d1-omni-600M model card for that model’s instructions.
The next useful milestones are more public evaluation of multimodal decision tasks and additional information about the experimental model’s speed and development status. Until then, the available results support testing d1-3B on the specific tasks and hardware measured, while broader claims about d1-omni-600M remain limited by the lack of published speed and vision or audio decision benchmarks.
real-time decision making edge devices
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
What did Liquid AI release?
Liquid AI released two open-weight decision models: d1-3B, which accepts text and images, and experimental d1-omni-600M, which accepts text with an image or text with audio.
How fast is d1-3B on edge hardware?
Liquid AI reports one-question latency of 16 ms on Jetson AGX Thor, 26 ms on Jetson AGX Orin 64 GB and 50 ms on Jetson Orin Nano. These are company-reported results for its tested setup, not a performance guarantee for every workload.
Does d1-omni-600M have published speed results?
No. Liquid AI says it is an early research release and that the company is not reporting speed figures for it in this release.
Are there public vision and audio decision benchmarks?
The release does not provide vision or audio decision benchmark scores. Liquid AI says the Decision Index version it used has a private vision split and that audio decision benchmarks remain an open problem.
Where can developers get the models?
Liquid AI says both models are available as open weights on Hugging Face. It also directs users to demos in its System One Arcade Hugging Face Space.
Source: rss
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.